
5 Things Worth Knowing About What Causes Server Timeout
The most critical insights into what causes server timeout reveal a mix of technical debt, architectural flaws, and unforeseen variables. These five factors aren’t exhaustive, but they account for the majority of outages across industries.1. Resource Exhaustion: When Servers Run Out of Breath
Servers have finite limits—CPU cycles, memory, and disk I/O—and when demand exceeds these, timeouts become inevitable. A single poorly optimized query can consume all available RAM, forcing the system to swap data to disk, which is orders of magnitude slower. This isn’t just a hardware issue; it’s often a software one. Developers may write inefficient algorithms that scale poorly, or databases may lack proper indexing, turning simple requests into resource hogs. The result? Under heavy load, the server hits its timeout threshold because it’s too busy processing requests to respond in time. The problem worsens in shared hosting environments, where multiple clients compete for the same pool of resources. A single high-traffic website on a shared server can starve others, leading to cascading timeouts. Cloud providers mitigate this with auto-scaling, but misconfigured scaling policies—like failing to set proper minimum/maximum instances—can leave systems vulnerable. Even with unlimited resources, poor code or unoptimized queries will eventually trigger what causes server timeout, proving that brute-force scaling isn’t a substitute for architectural discipline.2. Network Latency: The Invisible Speed Bump
Not all timeouts stem from server-side failures. Network latency—the delay between a request and its response—plays a silent but critical role. High latency can push response times over the timeout limit, even if the server itself is functioning perfectly. This is particularly common in geographically distributed systems, where requests must traverse multiple hops between data centers, ISPs, or CDNs. A single congested router or a failing peering link can introduce delays that turn a 200ms response into a 5-second timeout. The issue isn’t just about distance. Poorly optimized DNS resolution, misconfigured load balancers, or even ISP throttling can exacerbate latency. For example, a website relying on a third-party API in a different region may experience timeouts if that API’s response time exceeds the client’s timeout setting. Developers often overlook this when setting timeout thresholds, assuming local conditions will apply globally. The solution? Implementing regional failovers, CDN caching, and adaptive timeouts that adjust based on real-time network conditions.3. Third-Party Dependencies: The Weakest Link in the Chain
Modern applications rarely operate in isolation. They rely on payment gateways, analytics tools, social media widgets, or external APIs—any of which can become the weak link. If a third-party service experiences a timeout, the entire application may stall, waiting indefinitely for a response. This is especially problematic in microservices architectures, where a single failed call can trigger a domino effect of timeouts across interconnected services. The risk is compounded by what causes server timeout in these dependencies: their own resource limits, DDoS attacks, or even routine maintenance. A well-designed system should include circuit breakers—mechanisms that fail fast and gracefully when a dependency is unavailable—rather than waiting for the timeout to expire. Yet many applications lack these safeguards, leaving them vulnerable to cascading failures that amplify the impact of a single point of failure.4. Denial-of-Service Attacks: When Malice Exploits Weaknesses
Not all timeouts are accidental. Distributed Denial-of-Service (DDoS) attacks deliberately flood servers with traffic, overwhelming their capacity to respond. Attackers exploit what causes server timeout by sending an overwhelming volume of requests, forcing legitimate users to wait—or be denied service entirely. Unlike resource exhaustion from organic traffic, DDoS attacks are targeted, often using botnets to generate millions of requests per second. The damage isn’t just immediate. Even after an attack subsides, servers may remain unstable due to degraded performance or misconfigured mitigation measures. Some attacks focus on specific layers—like DNS amplification or SYN floods—to bypass basic firewall protections. The solution requires a multi-layered approach: rate limiting, anycast routing, and real-time traffic analysis to distinguish legitimate spikes from malicious ones.5. Configuration Errors: The Human Element in Digital Failures
Software is only as good as its configuration. A misplaced semicolon in a script, an incorrect timeout value in a load balancer, or an unpatched vulnerability can turn a stable system into a ticking time bomb. For example, setting a timeout threshold too low may cause premature failures, while setting it too high risks prolonged outages. Similarly, failing to implement proper connection pooling can lead to database timeouts under load. Even well-intentioned changes—like deploying a new feature without load testing—can introduce instability. Configuration drift, where settings diverge across environments (dev, staging, production), is another common pitfall. The result? A system that works in testing but fails spectacularly in the wild. Automated configuration management and infrastructure-as-code practices can reduce these risks, but they require discipline—something often overlooked in fast-moving environments.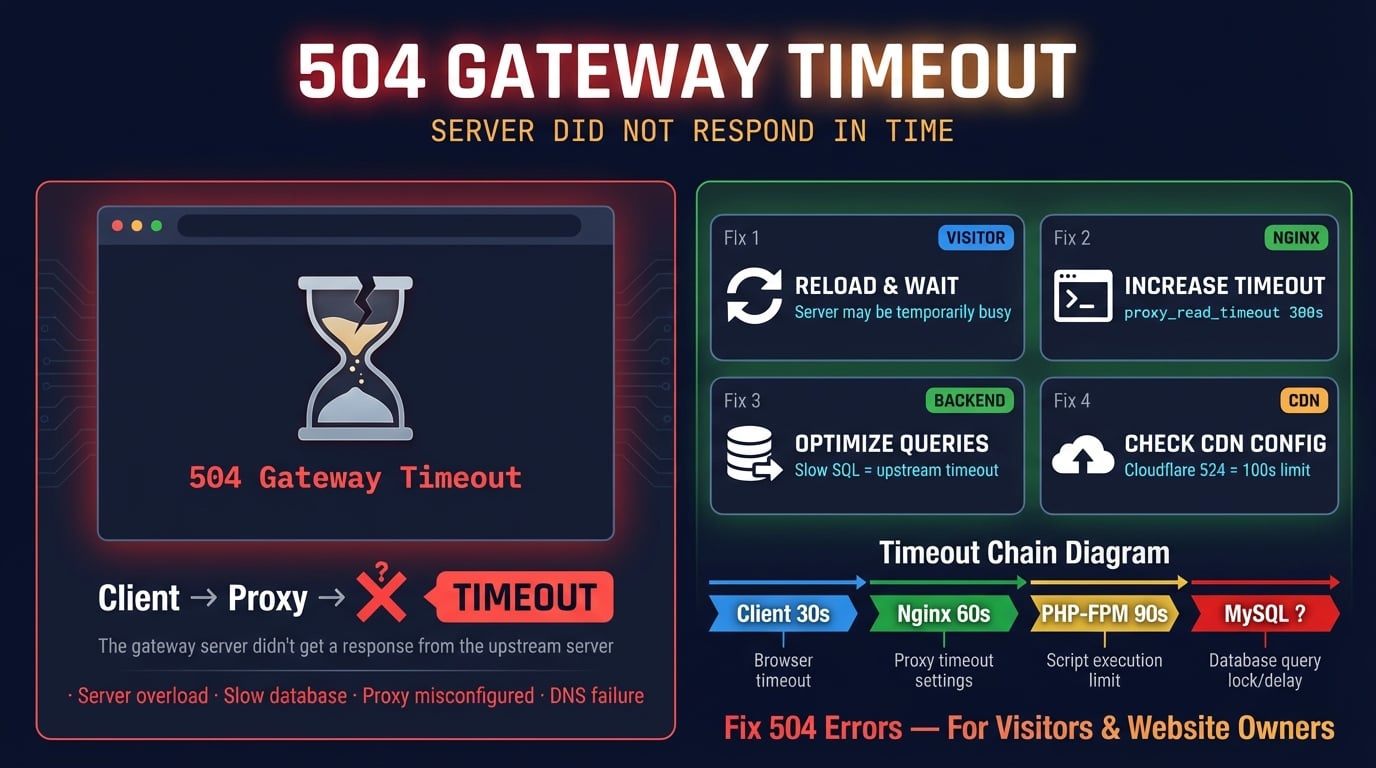
How These Facts Connect
The five factors behind what causes server timeout don’t operate in isolation. They intersect in ways that amplify failures. For instance, a DDoS attack (factor 4) can trigger resource exhaustion (factor 1), while network latency (factor 2) may mask the true cause of a timeout, making it harder to diagnose. Third-party dependencies (factor 3) often introduce latency or fail silently, exacerbating the problem. Meanwhile, configuration errors (factor 5) can turn any of these issues into a systemic crisis. The most resilient systems address these factors holistically. Load testing simulates traffic spikes to identify resource bottlenecks before they occur. Circuit breakers and retries handle third-party failures gracefully. Network monitoring detects latency issues early, and automated scaling prevents resource exhaustion. Even DDoS protections rely on understanding how attackers exploit what causes server timeout—whether through volumetric attacks or application-layer exploits. The table below compares the key factors and their mitigation strategies:| Factor | Primary Cause | Common Symptoms | Mitigation Strategy | Example Tool/Technique |
|---|---|---|---|---|
| Resource Exhaustion | CPU/memory/disk limits reached | Slow responses, 500 errors, crashes | Optimize code, implement auto-scaling | Kubernetes Horizontal Pod Autoscaler |
| Network Latency | High round-trip time or congestion | Timeouts, delayed API responses | CDN caching, regional failovers | Cloudflare, AWS Global Accelerator |
| Third-Party Dependencies | External service failures | Cascading timeouts, partial outages | Circuit breakers, retry policies | Hystrix, Resilience4j |
| DDoS Attacks | Malicious traffic overload | Sudden spikes, connection drops | Rate limiting, anycast routing | Akamai Prolexic, Cloudflare DDoS Protection |
| Configuration Errors | Misconfigured settings or drift | Intermittent failures, inconsistent behavior | Infrastructure-as-code, automated testing | Terraform, Ansible |

Conclusion
Understanding what causes server timeout isn’t just about reactive troubleshooting—it’s about designing systems that anticipate failure. The most robust architectures combine technical safeguards with operational discipline. Load testing, redundancy, and real-time monitoring are table stakes; what separates high-performing systems is the ability to detect and mitigate issues before they escalate. Yet even the best-prepared teams face unexpected challenges, from zero-day exploits to unprecedented traffic surges. The key takeaway? Server timeouts are rarely the result of a single mistake. They’re the product of systemic vulnerabilities—whether in code, infrastructure, or process. By addressing these factors proactively, organizations can reduce downtime, improve user experience, and avoid the financial and reputational costs of failure. The goal isn’t perfection, but resilience—the ability to absorb shocks and recover quickly when what causes server timeout strikes.Comprehensive FAQs
Q: Can a server timeout be caused by a user’s internet connection?
A: Indirectly, yes. If a user’s ISP throttles requests or their local network is congested, the server may not receive the request in time, triggering a timeout on the client side. However, true server timeouts occur when the server fails to respond within its configured threshold, regardless of the client’s connection. Tools like ping or traceroute can help distinguish between client-side and server-side issues.
Q: How do I set an appropriate timeout value?
A: Timeout values depend on the application’s requirements and network conditions. A common starting point is 30 seconds for HTTP requests, but this can vary. Factors to consider include:
- Expected response time under normal load
- Network latency between client and server
- Third-party dependency response times
Q: Why do timeouts sometimes occur during peak hours?
A: Peak hours often coincide with increased traffic, which can overwhelm server resources or exhaust database connections. If the system lacks auto-scaling or load balancing, requests may queue up, exceeding the timeout limit. Additionally, third-party services (e.g., payment processors) may also experience congestion, propagating delays. Load testing during expected peak periods can reveal these bottlenecks before they impact users.
Q: Are there tools to automatically detect and fix timeouts?
A: Yes, but with limitations. Tools like New Relic, Datadog, or Prometheus monitor response times and can alert teams to potential timeouts before they occur. Automated fixes (e.g., restarting failed services) are possible but risky—false positives can cause unnecessary disruptions. The best approach combines monitoring with manual review and proactive scaling.
Q: Can a DDoS attack be mistaken for a server timeout?
A: Yes. A DDoS attack can flood a server with requests, causing it to drop legitimate connections or fail to respond within the timeout window. However, DDoS attacks often exhibit patterns—sudden spikes in traffic from unusual sources—that differ from organic load. Tools like Cloudflare or AWS Shield analyze traffic anomalies to distinguish between malicious and legitimate timeouts.
Q: How does caching reduce the risk of timeouts?
A: Caching stores frequently accessed data (e.g., HTML pages, API responses) in memory or a CDN, reducing the need to query slower backend systems. This lowers CPU and database load, minimizing resource exhaustion. For example, a cached product page on an e-commerce site reduces server workload during traffic spikes, lowering the chance of what causes server timeout. Techniques like Redis or Varnish are commonly used for this purpose.
Q: What’s the difference between a server timeout and a connection timeout?
A: A server timeout occurs when the server takes too long to respond to a valid request, typically due to internal processing delays or resource limits. A connection timeout, however, happens when the client fails to establish a connection with the server at all—often due to network issues, firewall blocks, or the server being down. The former is a backend problem; the latter is usually a network or availability issue.
